Blog Archives

Data Sovereignty Is an Infrastructure Problem

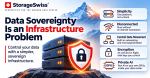
StorageSwiss featured image: Data Sovereignty Is an Infrastructure Problem, with a server stack and padlock shield and five requirements: simplicity, disconnected operation, control data movement, encryption and private AI

Data sovereignty is an infrastructure problem. Keeping data in-country is only residency, and a foreign provider can still be compelled to hand it over. Data center inflation and sovereignty rules now favor bringing workloads home, and this post lays out what sovereign infrastructure software requires, from disconnected operation to nested multitenancy, and why collapsing the stack matters most for midsize IT.
Posted in Article, Blog

The vSAN Cost of Surviving Double Drive Failure

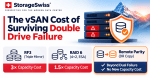
The vSAN Cost of Surviving Double Drive Failure: RF3 triple mirror at 3X capacity cost, RAID 6 4+2 ESA at 1.5X capacity cost, and remote parity from a DR copy that protects beyond dual failure with no new capacity cost

Surviving a double drive failure in vSAN ESA takes RAID 6, VCF licensing, at least six NVMe hosts and rebuilds that compete with production for CPU and network. Remote parity takes a different path. It uses the copy of data already kept at the DR site to supply missing blocks inline, protects beyond two failures and runs on lower-cost hard drives.

Posted in Article, Blog

What to Look for in a vSAN Alternative

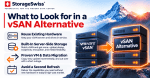
What to Look for in a vSAN Alternative: reuse existing hardware, built-in server-side storage, proven VM and data migration, and avoiding a second hardware refresh, with VMware vSAN servers moving to a vSAN alternative

Leaving VMware means leaving vSAN, so choosing a vSAN alternative means replacing the storage layer too. The right vSAN alternative runs on the servers and drives vSAN uses today, includes built-in server-side storage that matches vSAN and improves on it, and moves VMs with a backup-style migration that keeps production on VMware until the cutover.

Posted in Article, Blog

Year One Was Easy. Day 367 Is the Real Test of a VMware Alternative

Most VMware alternative evaluations focus on Day 1 migration and Day 2 operations. Day 367, the first expansion, is the real test. A year from now, servers, memory and flash will cost more, new servers will take months to arrive, and private AI will likely be on the project list. Extending server life, adding drives to open bays, mixing server vendors and pooling GPUs let midsize IT grow without a forklift budget.

Posted in Article, Blog

Why HCI Fell Short for Midsize IT, and What a VMware Alternative Needs Instead

HCI was designed for midsize IT and promised simpler operations and lower hardware costs. It delivered neither. Separate code bases behind one GUI looked simple on Day 1, then Day 2 quickly exposed them. Here is why HCI fell short and why midsize IT needs an infrastructure operating system instead.

Posted in Article, Blog

VMware Migration Requirements: What to Look For in a VMware Alternative

VMware migration requirements start with one goal: reduce cutover to a reboot by powering off the VM on VMware and powering it on under the new platform. Five capabilities get you there: initial data seeding with production still running, a maintained VMware state, multi-tenancy, incremental updates and independent snapshots. Here is what to look for in each one.

Tagged with: ,
Posted in Article, Blog

Hybrid Storage Failed Once. Will It Fail Again?

Hybrid storage failed the first time when the caching and tiering logic sat inside the array controller, behind the storage network and out of IT’s control. With flash now at $706 per terabyte and a 24 TB hard drive at $56, the question is back. Here is what changes when tiering runs inside the infrastructure software.

Posted in Article, Blog

Resiliency: HCI or AFA?

Resiliency: HCI or AFA? An all-flash array and HCI servers compared across drive, controller, server, VM, and site failures

HCI or AFA for your VMware exit? A modern all-flash array and a well-designed HCI cluster handle a single drive failure about equally well. The differences appear at controller and server failures, past the protection limit, and at recovery. This analysis compares how each design survives failure and explains why delivering HCI resiliency takes a fully integrated infrastructure software platform such as VergeOS.

Tagged with: ,
Posted in Article, Blog

Veeam Application-Consistent Backup Without the Guesswork

A crash-consistent backup and an application-consistent backup are not the same guarantee. On VergeOS, Veeam’s Deployment Toolkit closes that gap, installing its own backup agent automatically and quiescing SQL Server and other applications before the backup fully completes. The difference decides what a restore actually delivers on the worst day of the job, every time.

Posted in Article, Blog

Rising Cloud Costs: The Case for Owning Hardware in 2026

Rising cloud costs are changing the economics of infrastructure. As component prices climb and cloud capacity tightens, moving workloads to the cloud no longer provides an easy escape from hardware inflation. Extending server life, using quality second-life enterprise hardware, and choosing an infrastructure platform that preserves hardware freedom can turn ownership into a significant cost and availability advantage.

Tagged with: ,
Posted in Article, Blog